The question
VQ-VAE-2 uses two codebooks: a top level meant to capture global structure (shapes, layout) and a bottom level, conditioned on the top codes, meant to capture local detail (texture, color). I implemented it from scratch on Imagenette (~9k images, 256×256) and ran seven experiments varying codebook normalization, latent dimension (8 vs 64), and perceptual loss.
Results
The runs that carry the story:
| Norm | Latent dim | Perceptual loss | Top util | Bottom util | LPIPS | rFID |
|---|---|---|---|---|---|---|
| yes | 64 | — | 3% | 5% | 0.4385 | 73.58 |
| no | 64 | — | 7% | 16% | 0.3936 | 55.15 |
| yes | 8 | — | 1% | 29% | 0.3863 | 57.84 |
| no | 8 | — | 98% | 100% | 0.3461 | 44.98 |
| no | 8 | 0.1 | 99% | 100% | 0.0967 | 34.76 |
| yes | 64 | 0.1 | 2% | 20% | 0.1198 | 40.56 |
What I learned
Three findings, in the order they surfaced.
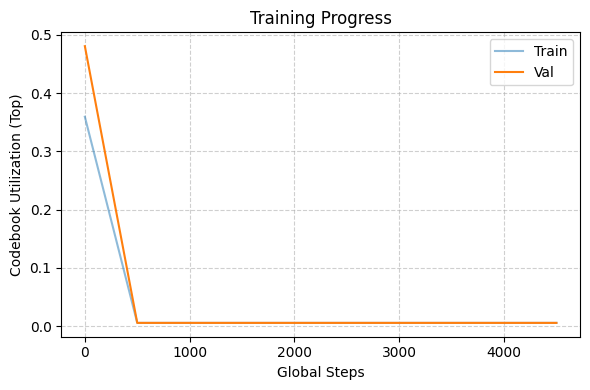
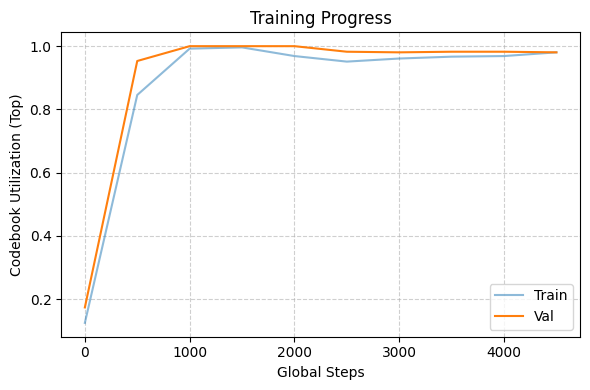
- Codebook utilization depended on both normalization and latent dimension, and they interact. Turning off normalization helped at both latent dims, but only restored near-full utilization at latent_dim 8 (1%/29% to 98%/100%). At latent_dim 64, utilization stayed low either way (3%/5% to 7%/16%).
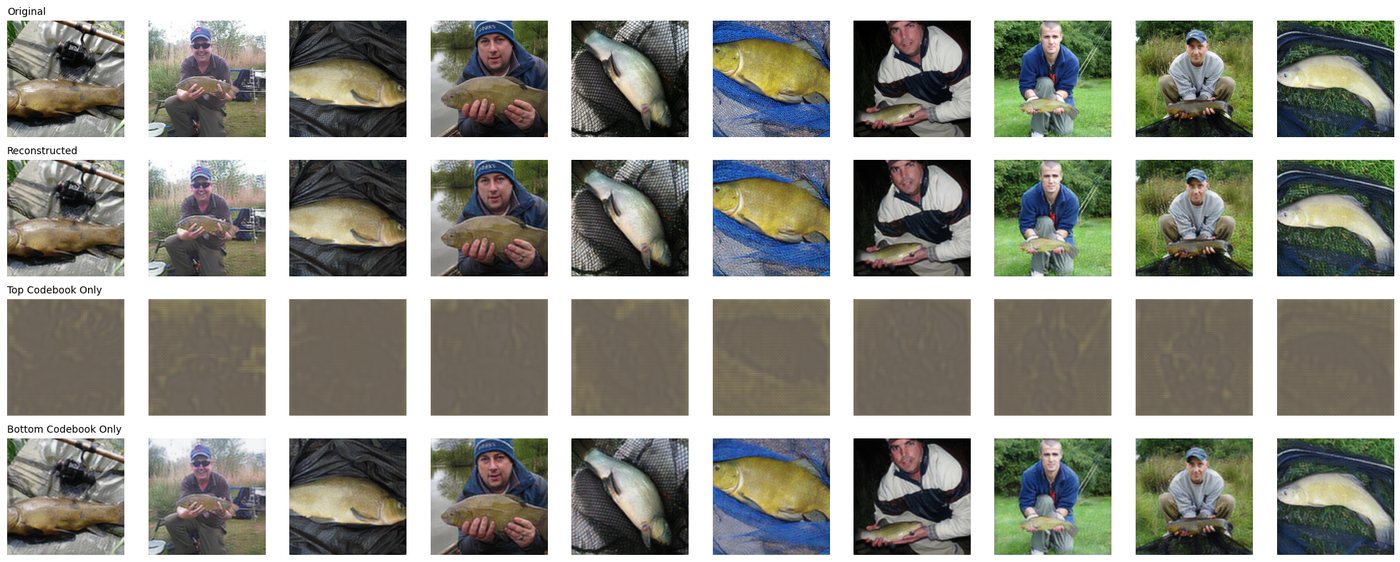
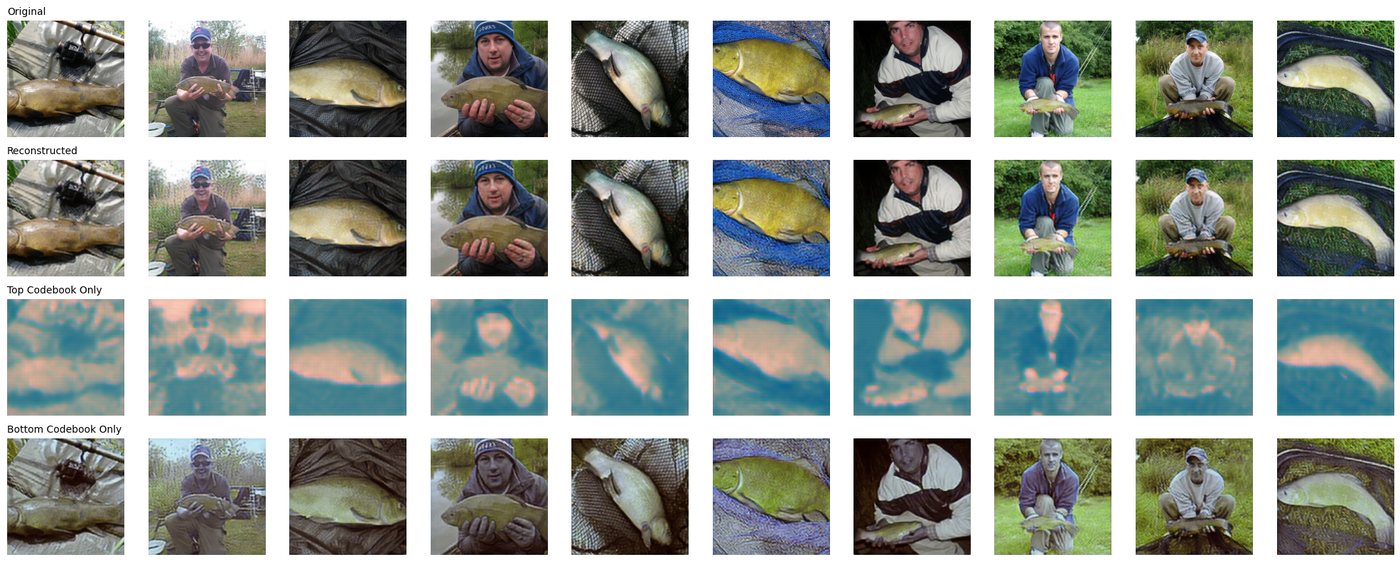
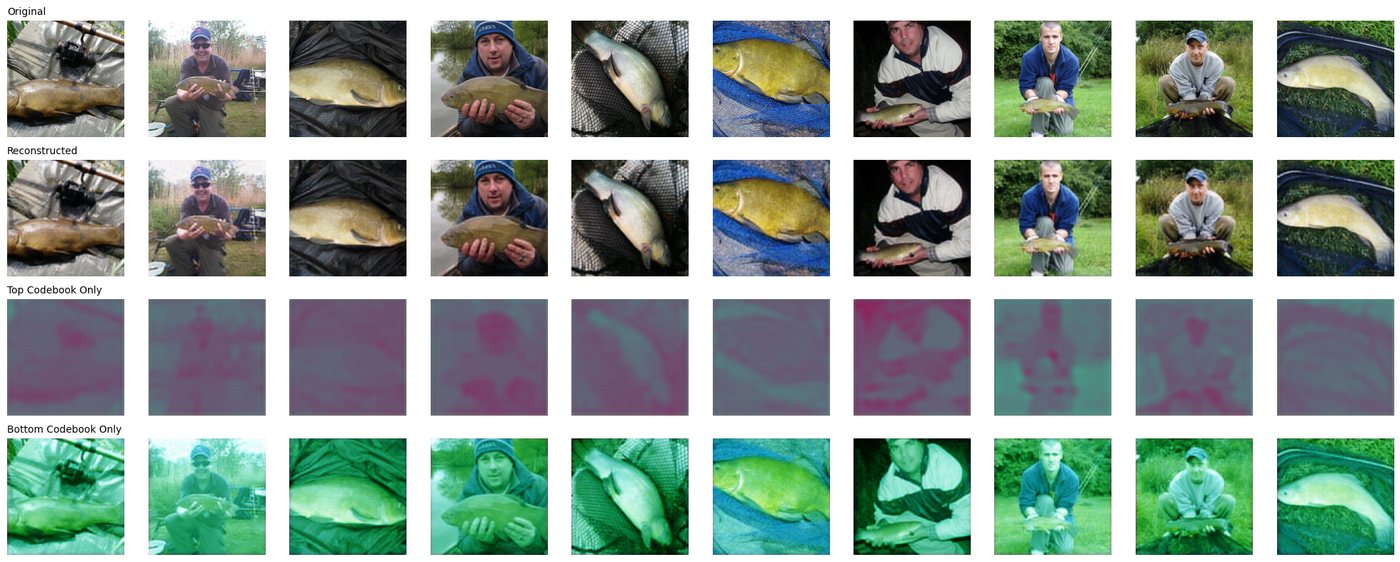
- Utilization is not the hierarchy story. Whether the two levels actually split structure from detail shows up in level-only reconstructions, not in utilization numbers. Decoding from the top codes alone should give a structural skeleton if the top level is doing its job; decoding from the bottom codes alone should give a recognizable image with the fine detail. That pattern held at latent_dim 64. At latent_dim 8, the top-only reconstruction faded and the bottom codes carried nearly the whole image, bypassing the hierarchical design.
- The first suspect was probably not the culprit. With perceptual loss at latent_dim 8, the top-only skeleton faded, and it looked like the loss was collapsing the top level. But comparing the two latent_dim 64 runs, with and without perceptual loss, the skeleton stayed clearly visible either way while LPIPS improved from 0.4385 to 0.1198. That points away from the loss and is consistent with a capacity explanation: at latent_dim 8 the top codes may simply not have room to hold global structure separately. The latent_dim 8 and 64 runs also differ in normalization, so I treat this as the likely explanation rather than a proven one. The loss itself was a straight win for sharpness: LPIPS dropped from 0.3461 to 0.0967 at the best configuration.