01
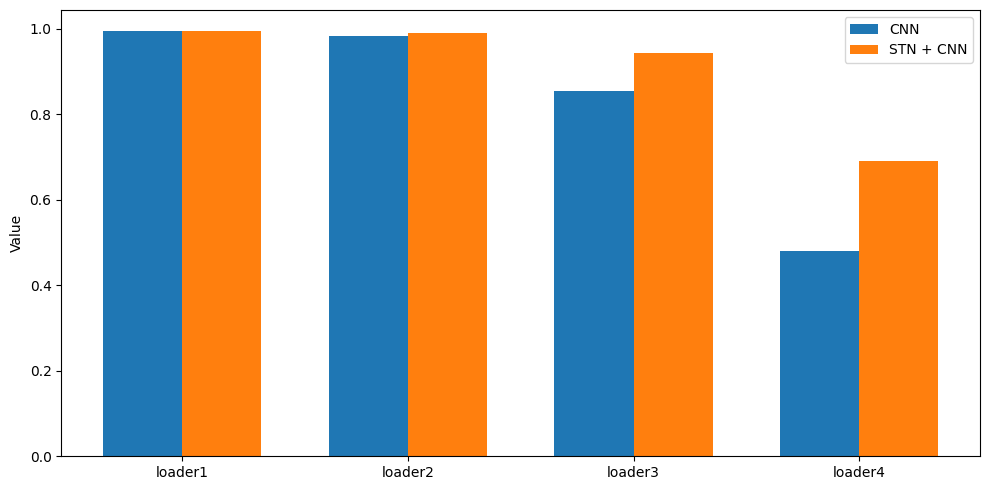
Does a network learn to undo distortion better than it tolerates it?
+21 points under extreme distortion, nothing on clean data.
Read the experiment ↗Controlled experiments on models I built from scratch. Implementations and full write-ups are on GitHub.
01
+21 points under extreme distortion, nothing on clean data.
Read the experiment ↗02
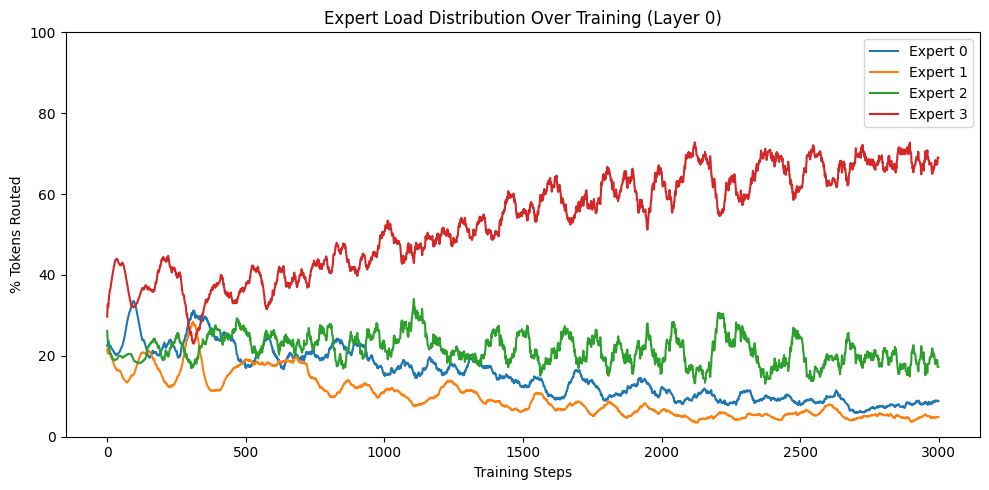
Three hypotheses, one survived.
Read the experiment ↗03
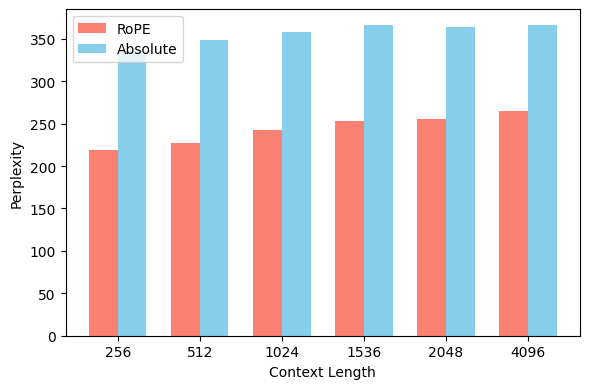
RoPE lower at every length to 4096; the expected failure of absolute embeddings did not reproduce.
Read the experiment ↗04
Why the paper keeps BatchNorm in train mode at inference, tested at batch size 1 vs 8.
Read the experiment ↗05
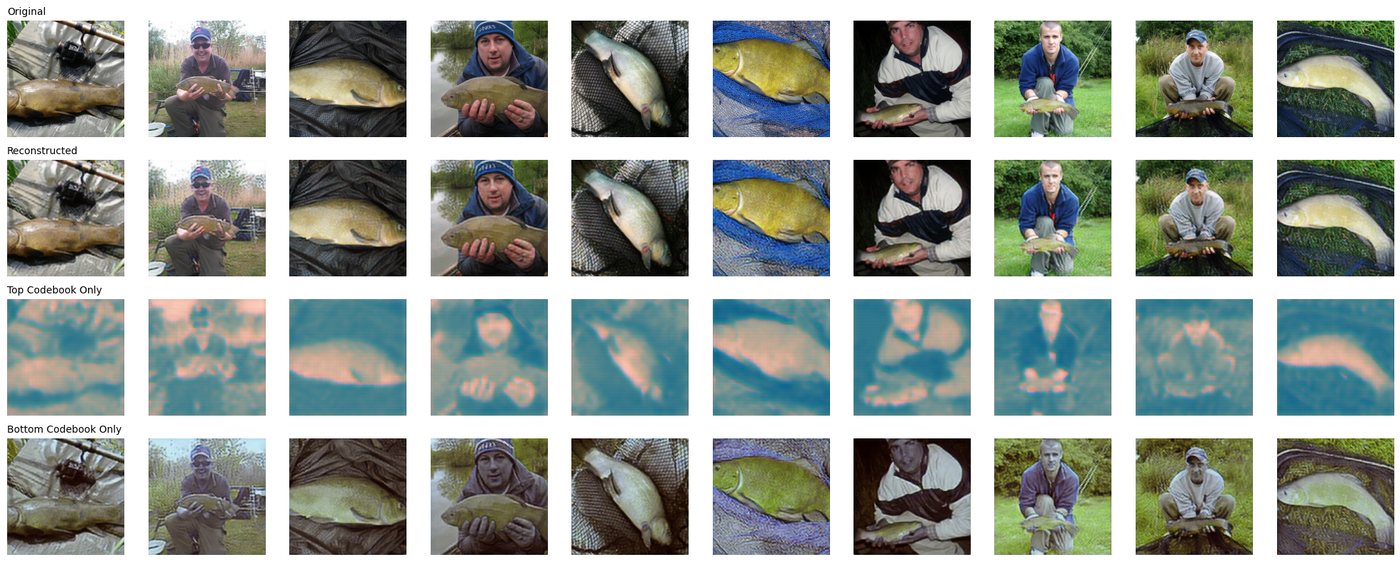
Perceptual loss cut LPIPS from 0.35 to 0.10; the faded top level was consistent with a latent-dimension capacity limit, not the loss.
Read the experiment ↗